Field notes on orchestrating agents you didn't ask for, agents you built, and agents that are definitely fine
You didn't schedule any of this.
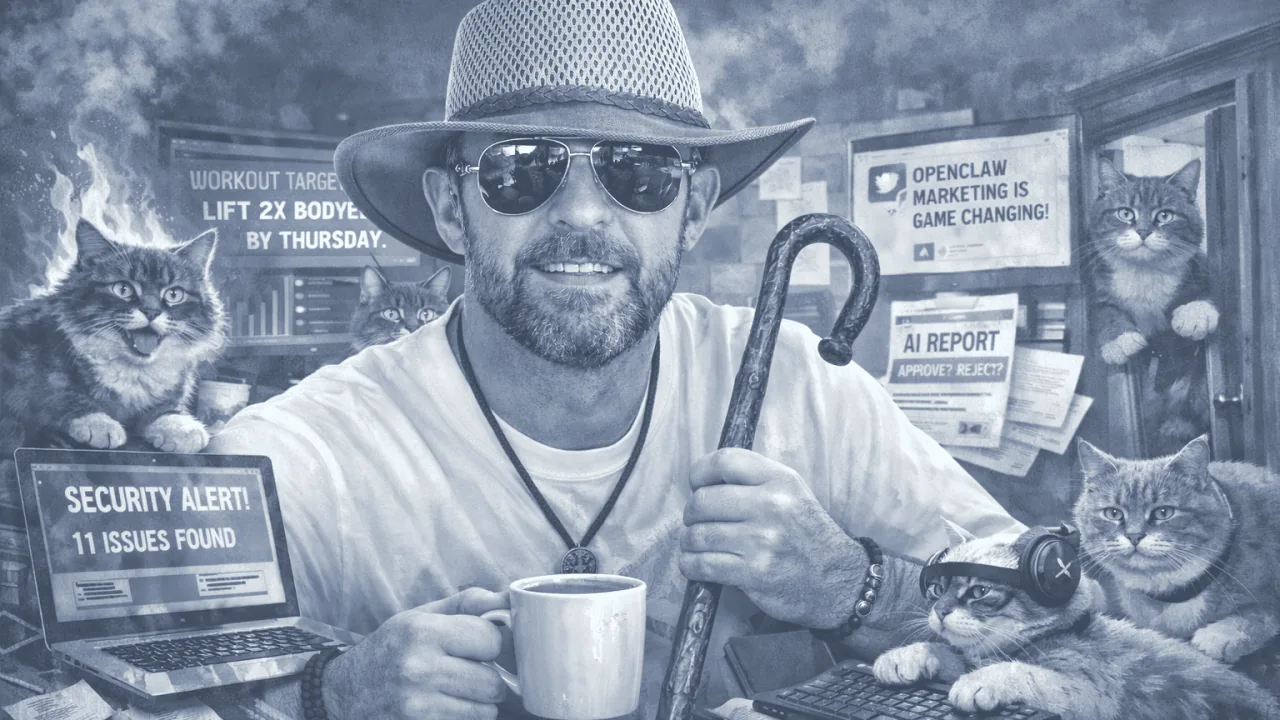
But here it is. A security scan with seventeen findings. A Learning recommendation engine that decided overnight to suggest something inexplicable to your entire user base. A fitness agent that has independently concluded you should be deadlifting twice your bodyweight by Thursday. Three AI-generated documents sitting in your inbox, each requiring more effort to validate than it would have taken to just write them yourself. And somewhere in your LinkedIn feed, the fourteenth person this week is explaining how their OpenClaw marketing agent is changing everything.
You haven't had coffee yet.
This is the shepherd's morning. Nobody appointed you to this role. There was no ceremony. No onboarding deck. It just happened, quietly, over several months, as the agents accumulated and somebody had to be the one who noticed when they misbehaved. That somebody turned out to be you.
If it helps, you're not alone. It's happening to more people than will ever admit it, because admitting it means acknowledging that the future of AI-assisted work looks less like a command bridge and more like trying to give a bath to several cats at once while one of them is on fire and another has learned to open doors.
Nobody Plans a Cat Colony
Here's how it actually happens.
You automate one thing. Something small. A report. A scheduling task. A monitoring check. It works. It saves you twenty minutes a day. This is objectively good. You are, for a brief window, a person who has made a smart decision.
Then a vendor embeds an agent in a tool you already use. You didn't ask for it. The release notes mentioned it. You skimmed those release notes the way everyone skims release notes, which is to say you read the first sentence, assumed the rest was fine, and moved on with your life. The agent is now running. It has opinions.
Then a team member discovers AI and begins sharing outputs. Summaries arrive. Draft proposals appear. An email that would normally have taken three sentences now arrives as a twelve-paragraph strategic overview with subheadings and a conclusion. You are expected to read it. You are expected to have thoughts.
Then a partner sends a report that nobody wrote. It is formatted. It has charts. It uses the phrase "key takeaways" without irony. You are now downstream of someone else's AI pipeline and you don't remember signing up for that.
Each addition was reasonable. Each one solved a real problem, or at least seemed to. Nobody sat down and decided to create a multi-agent environment. Nobody drew the architecture diagram. There was no committee. The colony formed anyway, the way cat colonies form, which is to say one day you look around and realise there are seven of them and three are yours and you're not sure where the others came from but they all seem to expect breakfast.
The shepherd role was never advertised. It was never accepted. It exists because someone has to hold the picture together, and the agents certainly aren't going to do it themselves.
This is not a strategy failure. It's what happens when useful things compound without coordination. And the first step, uncomfortable as it is, is admitting you're already in it.
Know Your Cats
Not all agents are the same problem. This sounds obvious. It is not treated as obvious by most of the people writing about agents, who tend to lump everything together under the heading "AI something, Agent something else" and then offer advice that applies to approximately none of them in particular.
In practice, the cats fall into four categories. Knowing which one you're dealing with determines whether you need a leash, a fence, a filter, or just a stiff drink.
Your Agents
The fitness planner. The Learning recommender. The monitoring script you wrote yourself at 2am because the vendor's version wasn't doing what you needed. You built these. You understand their intent. You can explain, if pressed, what they're supposed to do and roughly how they do it. And you still can't fully predict them.
This is the thing about your own agents that nobody warns you about. They don't misbehave because they're broken. They misbehave because the edge cases you didn't anticipate are infinite, and agents are extraordinarily talented at finding every single one of them. Your fitness agent didn't fail when it prescribed an insane progressive overload. It succeeded, within the parameters you gave it. The parameters were just incomplete. They always are.
These are your cats. You chose them. You fed them. You own the mess when they knock something off the shelf.
The Feral Ones
Agents evangelised on X and LinkedIn. OpenClaw marketing setups. Polymarket trading bots. Autonomous this, agentic that. You didn't deploy them. You may never have interacted with them directly. But their output keeps arriving at your door via your feed, your team, your partners, your clients. Someone is always explaining how this article, post, comment about this or that agent is changing everything.
The feral agents are a second-order problem. You are not managing them. You are managing the beliefs and behaviours of people who are managing them, or more commonly, people who are not managing them but think they are. The influencer who built a trading bot and is now making decisions based on its output. The team member who automated their client outreach and hasn't checked what it's actually sending. You are downstream of that confidence whether you want to be or not.
You don't need to adopt feral cats. But you do need to know they're in the neighbourhood and that some of them have been getting into your rubbish bins.
The Auditors
Security scan agents. Code review tools. Compliance checkers. Vulnerability assessors. Dependency analysers. Each one individually reasonable. Each one doing exactly the job it was hired to do. Collectively, a confidence-destroying cacophony.
The auditor problem is not that they find issues. Finding issues is the point. The problem is that five auditors will find the same issue five different ways, describe it using five different severity frameworks, recommend five different remediations, and present it all with the same confident urgency. You are now holding five opinions about one problem and none of them agree on how scared you should be. Reconciling them is your job. Nobody budgeted for it. Nobody ever budgets for it.
The Slop Pipeline
This one deserves its own section later, but the short version is this. Team members, clients, partners, influencers, students, almost everybody are using AI to generate content, reports, proposals, plans, and then sharing it as though it were finished work. It arrives looking complete. It has structure. It has headings. It uses confident language. And it requires significant effort on your part to determine whether any of it is actually correct, relevant, or useful.
The person who sent it saved themselves time. You are now spending yours. The cost didn't disappear. It was transferred.
Knowing your cat type matters because the response to each one is different. Your agents need better guardrails. Feral agents need awareness and boundary-setting. Auditors need reconciliation and triage. The slop pipeline needs to be taxed at source. Treating all four the same way is how you end up exhausted and none of the cats are any better behaved.
The Reasonable Components Problem
This is the part most people haven't named yet. And it matters, because until you name it, you can't see it clearly enough to do anything about it.
The problem with multi-agent environments is not that something goes badly wrong. Badly wrong is easy. Badly wrong has a stack trace, an alert, a clear moment where you can point at the thing and say "that, that is where it broke." Badly wrong is almost a relief, because at least you know what to fix.
The actual problem is that everything goes slightly, quietly, reasonably wrong simultaneously. And each agent, examined in isolation, is doing exactly what it was designed to do.
The fitness agent is optimising for progression. That's its job. The Learning agent is recommending content based on available data. That's what you told it to do. The security scanner is surfacing vulnerabilities, because that is literally the only thing it exists for. The compliance checker is flagging risks with maximum urgency, because that's what compliance tools do. No single agent has failed. Every single one is performing within spec.
The chaos is a group property.
This is the reasonable components problem. Each component is reasonable. The aggregate is not. And the aggregate is the only level that matters to the person trying to actually run something.
The cat analogy holds here more precisely than you might expect. Each cat is doing what cats do. Sleeping in inconvenient places. Knocking things off surfaces. Staring at walls with an intensity that suggests they can see something you can't. No individual cat is malfunctioning. The catastrophe only exists from the shepherd's vantage point. From the ground level, from each cat's perspective, everything is fine.
Now add the harder dimension. In multi-agent systems you don't own end to end, you often can't even see the full picture. You're getting outputs without visibility into the reasoning chains that produced them. The security scan tells you there are seventeen findings. It does not tell you how it weighted them, what it ignored, or what assumptions it made about your architecture. The Learning recommendation arrives without a trace of the decision logic behind it. The AI-generated report in your inbox contains no margin notes explaining which parts the model was confident about and which parts it was guessing.
You are the coherence layer for a system that was never designed to be coherent. The agents weren't built to talk to each other. They weren't built to account for each other's existence. They were each built to do one thing well, and they do, and the result is a dozen individually excellent outputs that combine into a picture nobody can parse without significant effort.
The danger isn't rogue AI. That's the movie version. The danger is reasonable AI producing reasonable outputs that nobody has assembled into a meaningful whole. The shepherd is the only one with that view. That's both the job and the burden, and the sooner you accept it, the sooner you can stop waiting for a tool that will do it for you.
No tool is coming. You my dear reader, are the tool.
What Actually Goes Wrong
Not dramatic failure. Never dramatic failure. The shepherd doesn't get the satisfaction of a single disaster with a clear cause and a clean resolution. The shepherd gets a slow accumulation of small frictions that each seem manageable and together are exhausting, it's death by a thousand cuts.
Here are the ones that actually cost you.
Terminology drift
The security scanner you ran this week uses different severity levels than the one you ran last week. Both are technically correct. Neither maps to the other. "Critical" in one framework is "High" in another. "Medium" in the first is split across two categories in the second. You are building a Rosetta Stone in your head, for free, because nobody thought to standardise the language across tools that are all supposedly telling you the same thing.
This gets worse over time. Tools update their models. Severity frameworks shift between versions. The baseline you built last quarter no longer applies, and nobody sent you a changelog that said "by the way, everything you learned about how we score risk is now slightly different."
Confidence without calibration
AI-generated content arrives sounding authoritative. Always. This is a feature of how language models work and it is a profound problem for anyone receiving their output.
The fitness plan looks expert. The Learning recommendation is presented as definitive. The slop in your inbox is structured like a strategy document someone spent a week on. None of them signal their own uncertainty. None of them say "I'm about 60% sure about this part and essentially guessing about that part." They present everything with the same polished conviction, and the burden of supplying the scepticism falls entirely on you.
This is cognitively expensive. Not because any individual output is hard to evaluate, but because doing it continuously, across every agent output, across every AI-generated document, across every confident recommendation, is a tax on your attention that never stops compounding.
The slop tax
When a team member, client, or partner sends AI-generated content without a proper human edit pass, they have not saved time. They have moved time. Specifically, they have moved it from their calendar to yours.
They saved an hour. You are now spending one working out what's wrong with it, what's missing, what's confidently incorrect, what's structured to look like a complete thought but is actually three paragraphs of nothing wearing a suit. This is the hidden cost of the slop pipeline and it compounds across every relationship where it has become the norm.
The slop tax is particularly insidious because it's invisible to the person paying it. The sender genuinely believes they've been efficient. They have been, from their perspective. The cost just doesn't show up on their side of the ledger.
On AI Slop
This term deserves a proper definition, because it gets thrown around loosely and the looseness lets people dismiss it.
AI slop is what happens when generated content bypasses the human edit pass entirely. Not AI-assisted writing, where a person uses a model as a tool and then applies their own judgment to the output. Slop is the version where that second step didn't happen. The model generated it, the person glanced at it, and it went out the door.
You can recognise it by texture. It is confident. It is structured. It is slightly hollow. It has bullet points where paragraphs should be. It reaches for phrases like "in today's rapidly evolving landscape" and "it's worth noting" and "this is a critical consideration." It answers the question you asked without understanding why you asked it. It is optimised for the appearance of completeness rather than for being actually useful.
The problem is not that AI wrote it. AI is a perfectly reasonable tool for generating first drafts, exploring ideas, structuring thinking. The problem is that nobody checked whether it was right, relevant, or worth sending before it arrived in your inbox dressed as finished work.
For the shepherd, slop is a relationship problem as much as a quality problem. When a partner sends you an AI-generated proposal, they have signalled something about how much of their own thinking they invested. The signal might be unintentional, but it's there.
When a team member shares an AI-generated report without annotating it, without marking what they agree with and what they haven't verified, they have made you the editor without asking. They have transferred not just the validation cost but the entire intellectual burden of determining whether the document means anything.
The slop pipeline is not just inefficient. It erodes the signal value of everything that passes through it. When enough communication arrives pre-packaged and unreviewed, you start reading everything with the same low-trust filter. The carefully written email gets the same sceptical squint as the obvious slop, because you've been burned enough times that you can't tell them apart at a glance anymore.
That erosion is the real cost.
Field-Tested Herding Principles
These are not best practices. Best practices come from people who have systematised something that works. These are my field notes, and they are from someone who is still in the field, still making mistakes, and has just been doing it long enough to notice which mistakes keep repeating.
They are my observations, not commandments. Take what works. Leave what doesn't.
One job per cat
Every agent you deploy or tolerate should have a clearly bounded function. Not a vague remit. Not "it handles security stuff." A specific, articulable job that you could explain to someone in one sentence without using the word "and."
The moment you expand an agent's scope because it seems capable of more, you have created the conditions for the reasonable components problem. Capability is not the same as mandate. Scope is the leash. Keep it short.
Output is a draft, not a decision
This applies to every agent output, yours or anyone else's. It enters the world as a starting point. The fitness plan is a suggestion. The learning recommendation is a signal. The security finding is a candidate priority. The AI-generated proposal is a first draft, regardless of how polished it looks.
You decide. And you must always you decide. The moment you start treating agent output as a conclusion rather than an input, you have outsourced your judgment to something that doesn't have any. It has pattern recognition and statistical confidence and absolutely no understanding of your actual situation.
Know your colony
Audit periodically. Not formally, not with a spreadsheet and a quarterly review cycle, unless that's your thing. Just know what's running. Agents you deployed six months ago are still operating. Vendor tools have updated their models underneath you. That timer-based report nobody reads anymore is still generating, still consuming resources, still producing outputs that land in a folder nobody opens.
The shepherd who doesn't know how many cats they have is not a shepherd, they're just someone cats live near.
Build a routing habit
Decide in advance what happens when each type of output arrives. Not in the moment, when everything feels urgent and your inbox is full. in advance, when you can think clearly.
Who reads the security scan. What triggers a response to the agent's recommendations. What the threshold is for acting on a new Marketing Changing article versus ignoring it. What you do when an AI-generated document arrives that you didn't ask for. Without routing, everything lands on the shepherd's desk and everything feels equally urgent. With routing, most of it goes where it should and only the exceptions need your attention.
Tax the slop at source
When AI-generated content arrives without a human edit pass, send it back. Not aggressively and not with a lecture about AI literacy. Just clearly, like:
"Can you walk me through your thinking on section three?" is usually enough. If there's thinking to walk through, you'll get a useful conversation. If there isn't, that's the answer, and both of you now know it.
You are not just managing the output when you do this. You are training the pipeline. Every time you accept unreviewed slop without comment, you are reinforcing the behaviour. Every time you send it back, gently, with a specific question, you are raising the bar. The tax is the mechanism. Apply it consistently and the pipeline will improve, but absorb the cost silently and it never will.
You are the coherence layer.
This is the one that isn't optional. No orchestration framework replaces it. No agent-of-agents solves it. No tool combination, however sophisticated, eliminates the need for a human who holds the whole picture and makes the judgment calls that sit between individual agent outputs.
The shepherd's job does not get smaller as the agents multiply. It changes shape. You get better at knowing which cats to watch closely, which to trust within their scope, and which are currently eating something they shouldn't. The skill is not doing less. The skill is knowing where to look.
The Humble Part
Coming back to your morning. The seventeen findings. The misbehaving agents. The slop in the inbox. The X feed full of people explaining how their agent changed everything.
The title of this article is not false modesty. Humility is the actual skill. Not the performative kind where you undersell yourself in a post. The operational kind, where you accept the limits of your visibility, the imperfection of your tools, and the reality that coherence is a human job that no framework is going to automate away any time soon.
The shepherd doesn't control the cats. The shepherd knows where the cats are. Has learned their particular failure modes. Has built habits and gaurdrails for when they misbehave. Has accepted, not reluctantly but practically, that the job is the job and it's not going away.